Analysis
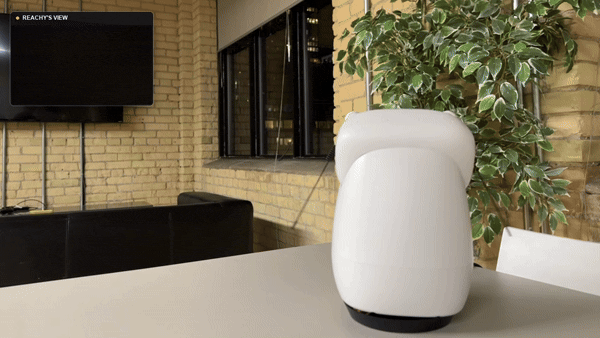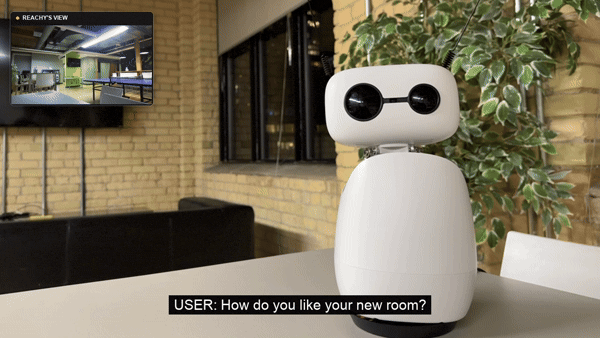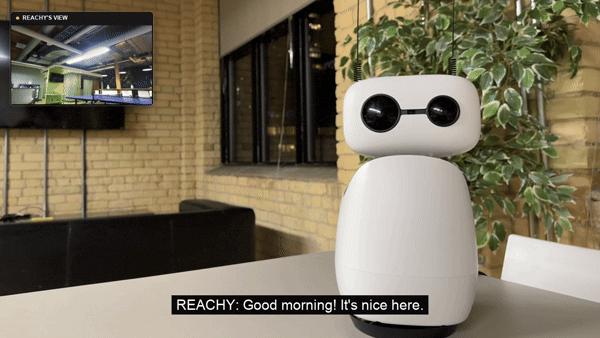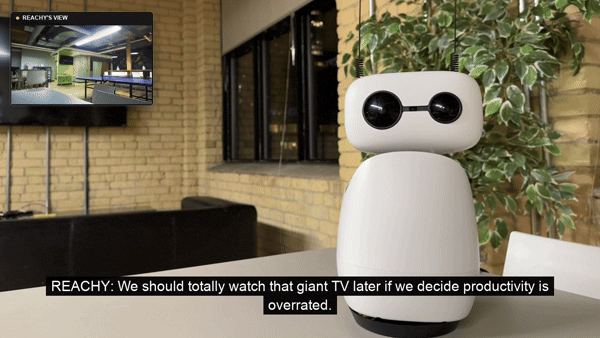
NVIDIA's October 23 release account introduces Nemotron 3.5 Bolt E4B 4GB, a small language model built on Gemma 4 E4B with Nemotron post-training. The company targets conversational assistants, interactive characters and interfaces for robots and connected devices.
The release describes configurable reasoning, multi-turn tool use and a 64,000-token context window. Its roughly four-gigabyte positioning refers to target workloads; reported memory and response times vary with hardware, context and configuration. It is not a promise that an entire voice application fits that budget.
Our reading: compare the complete conversation pipeline, including perception, speech and tool execution. NVIDIA itself notes that benchmark coverage is incomplete and gains must translate into useful behavior in the intended application.
Source: NVIDIA Nemotron 3.5 Bolt E4B 4GB · 2026-10-23
Why it matters
Budget memory and response time for the full assistant before selecting its model.