Analysis
Nanbeige LLM Lab's official model card presents Nanbeige4.3-33B as a model for coding and professional agent tasks, released under Apache 2.0. The lab also positions it as a teacher for a future pipeline of smaller models.
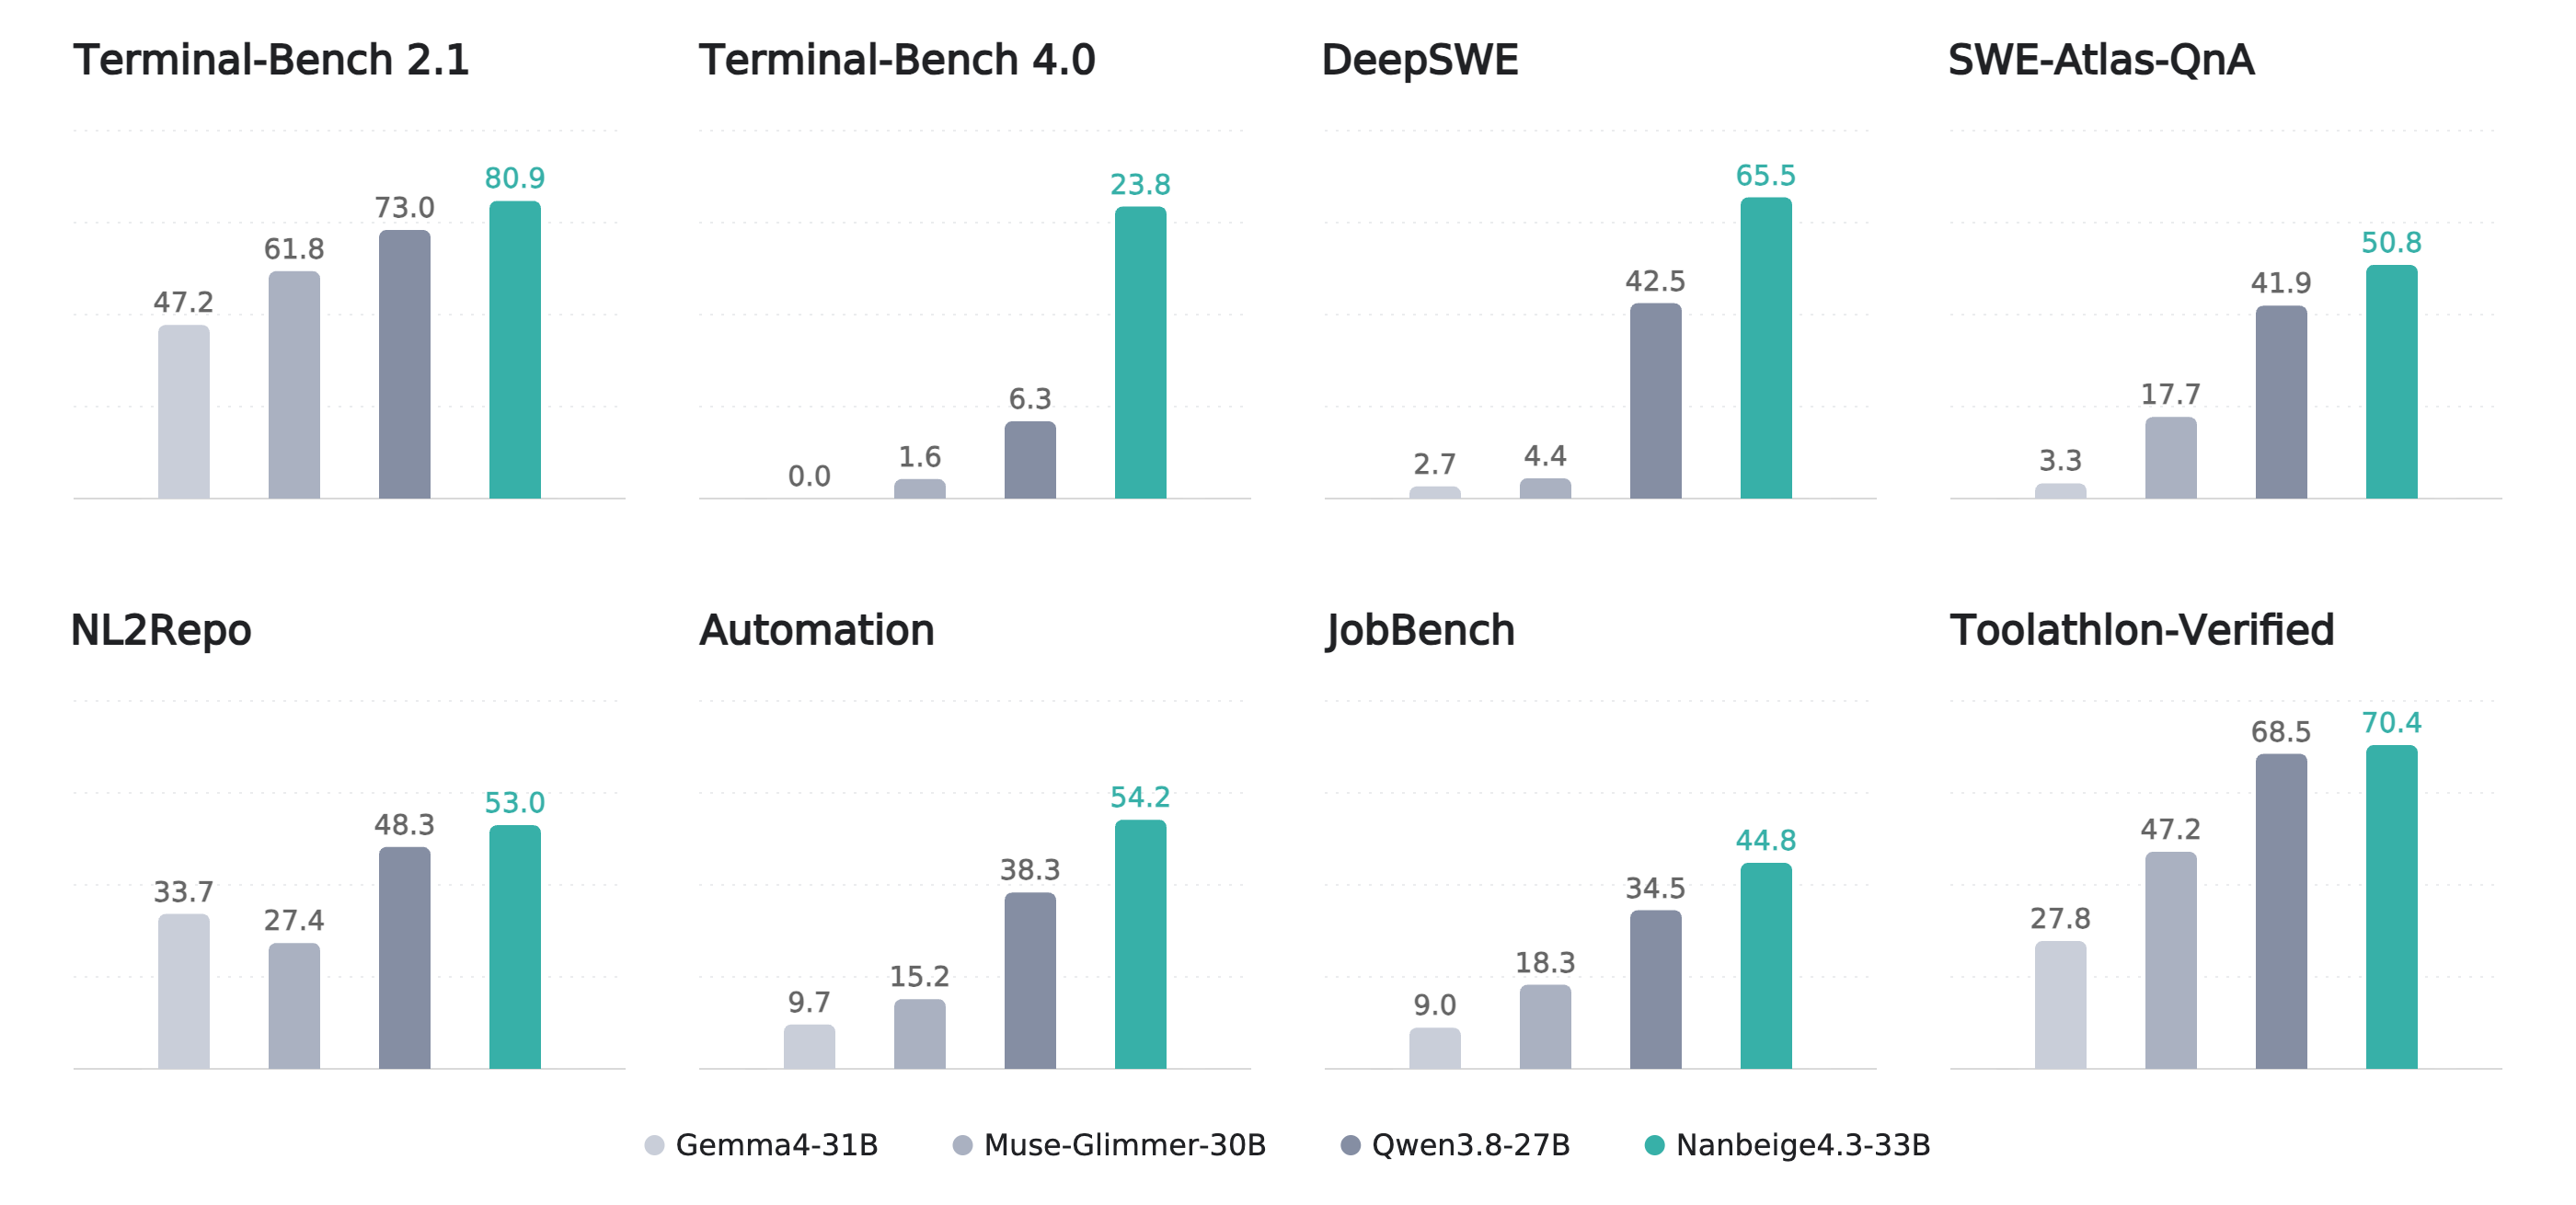
The card reports strong results across its comparison table, including 80.9 on Terminal-Bench 2.1. That does not mean it leads every task: the same table shows a lower SWE-Bench Pro score than Qwen3.8-27B. These are the developer's evaluations, with specified harnesses and thinking settings.
Our reading: an available model and a proposed distilled successor are separate deliverables. The released model can be evaluated today; the smaller-model plan remains a plan. Workload-specific testing matters more than a single headline benchmark.
Source: Nanbeige4.3-33B — official model card
Why it matters
A permissive release expands evaluation choices without proving suitability for a particular coding workflow.